Key takeaways
- The measured unit is one logged callback request with a defined trigger and closing event.
- The design separates observed evidence from operational interpretation.
- The conclusion remains bounded by the stated limitations.
Research question
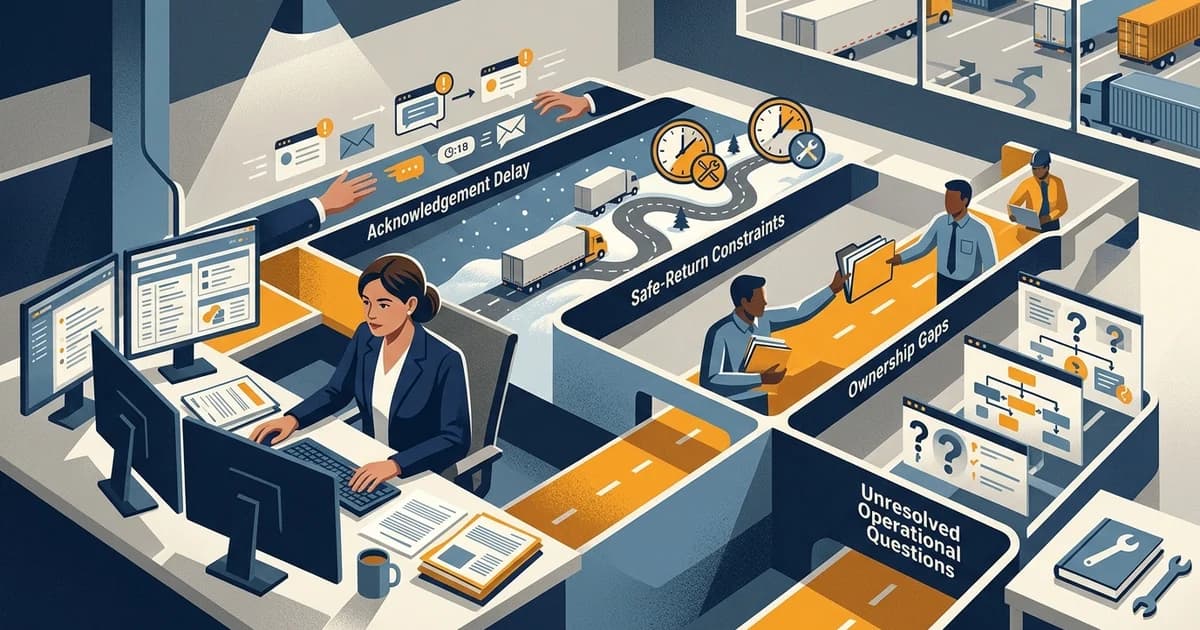
Can callback age identify a weak dispatch handoff without penalizing safe driving or confusing acknowledgement with resolution?
This question matters to a trucking back office because a familiar dashboard field can appear more certain than the underlying record. The study treats one logged callback request with a defined trigger and closing event as the unit of analysis. It does not treat a person, driver, customer, or fleet as the unit. That choice keeps the work focused on evidence quality and process design rather than unsupported judgments about performance.
Evidence reviewed
Federal distracted-driving guidance supports communication practices that do not demand unsafe device use, worker-fatigue resources add scheduling context, and federal operating rules show why operational interpretation belongs with responsible carrier staff. Queue timestamps alone do not explain delay. The review used the genuine source URLs listed below and examined them on August 19, 2026. Source material was used to define context, provenance, and measurement boundaries. It was not used to invent TruckingVA results, carrier practices, or universal thresholds.
The evidence hierarchy begins with preserved source records. A direct observation with a known time and identifier carries different information from a planned event, copied value, or later summary. Repetition does not create independence when several records copied the same original. For that reason, the study keeps source class and lineage visible before comparing outcomes.
Methodology
Observe a consecutive two-week sample. Record request time, channel, urgency class, driver duty context if legitimately available, acknowledgement, first safe response, owner assignment, resolution, and reopen event. Analyze these intervals separately and review outliers with source messages rather than memory. The sampling rule must be written before records are examined so that difficult cases are not added or removed after a pattern appears. The reviewer should record exclusions and explain why each excluded record cannot support the selected unit.
Each row should preserve the original identifier, event time, received time, source class, reviewer, classification, and any missing field. Derived intervals belong in separate columns. If two source records disagree, both values remain visible. A resolution field can describe the owner’s later decision, but it must not overwrite the observed disagreement.
To test repeatability, a second reviewer should independently classify at least one fifth of the sample using the same definitions. Differences should be discussed by category. If reviewers repeatedly disagree, revise the definition and rerun the affected sample rather than choosing whichever classification produces a cleaner result. Report counts with denominators and missing-data counts. Avoid a single blended score that conceals why evidence was weak.
Worked evidence example
A driver receives a nonurgent request while moving and returns it after parking. The acknowledgement interval is long, but the safe-response interval may be appropriate. A separate request acknowledged quickly but reassigned three times has a short first interval and a long ownership interval. This example shows why sequence and provenance matter. The first question is what each source actually records. The second is whether the sources describe the same event. Only then should an operations owner consider what action, if any, is justified.
A virtual assistant can prepare the event table, verify identifiers, locate source records, and identify rows that do not meet the written definition. Administrative staff should not decide cargo security, safety compliance, card misuse, contractual sufficiency, or driver conduct. Those conclusions require the carrier’s accountable owner and may require specialized advice.
Analysis plan
Begin with a flow count: eligible records, excluded records, analyzed records, records missing a critical field, and records with conflicting evidence. Then describe each source class and classification. Cross-tabulate source class with unresolved status to see whether one handoff creates disproportionate uncertainty. Review raw evidence for every apparent outlier because a rare value may reflect an identifier mistake rather than an unusual operation.
Time fields require special care. Save the original timezone or offset when available and state the conversion rule. Do not infer event order from message position alone. Where precision differs, retain the less precise value rather than adding invented minutes or coordinates. If one field is generated later from another, label the dependency so reviewers do not count copied values as confirmation.
The result should answer a carrier decision in plain language. It may support a narrower intake rule, a clearer source label, a targeted reconciliation queue, or no change while more evidence is collected. State what new evidence would change the classification. This turns the report into a reproducible decision aid instead of a permanent verdict.
Limitations
Duty context may be missing, message timestamps can differ by platform, urgency labels may be applied after the fact, and a short study may miss peak periods. The design cannot judge individual performance, fatigue, safety compliance, or the quality of an operational decision. Observational records also reflect local software, staff habits, customer requirements, and access permissions. Missing evidence can mean that an event did not occur, that it was not captured, or that the reviewer lacks access. The design cannot distinguish those explanations without additional evidence.
No association in this study proves causation. Reviewer agreement does not prove that an underlying event was correct; it only shows that the written classification can be applied consistently. Public guidance can establish context but cannot determine the facts of a private movement. Results should be versioned when records are corrected or the scope changes.
Conclusion
Queue age becomes useful only after it is split into acknowledgement, safe response, ownership, and resolution intervals. The resulting evidence points to workflow friction without rewarding unsafe communication. The evidence-led conclusion is intentionally narrow. Preserve source lineage, define the denominator, disclose exclusions, and keep operational judgment with the qualified owner. These safeguards allow a trucking virtual assistant to improve record visibility without converting administrative convenience into false certainty.
Practical use for fleet back-office teams
Start with a small prospective sample and one named reviewer. Publish the field definitions internally before collecting observations. During the sample, let the assistant maintain the evidence table and a separate question queue. Meet with the accountable owner to resolve definition problems, not to pressure every uncertain row into a closed status.
At the end of the period, retain the population list, exclusion notes, source links, classification guide, reviewer differences, and dated conclusion. A later review should be able to reproduce why each row was included and how it was classified. If that is not possible, the result is a discussion prompt, not reliable research evidence.
Sources
Sources and citations
- https://www.fmcsa.dot.gov/driver-safety/distracted-driving, retrieved 2026-08-19
- https://www.osha.gov/worker-fatigue, retrieved 2026-08-19
- https://www.ecfr.gov/current/title-49/subtitle-B/chapter-III/subchapter-B/part-392, retrieved 2026-08-19